Structured Gaussian Processes for Human Motion Prediction
Robots that share space with people need motion predictions with reliable uncertainty, not just accurate means. A structured multitask Gaussian process predicts 2 s of full-body motion in closed form. On Human3.6M, it assigns higher likelihood to the true motion than Motron and DLow at every prediction step, with about seven times fewer parameters than Motron.
A robot working alongside a person can use calibrated uncertainty to size its safety margins. Overconfident predictions invite collisions, while overly conservative ones make the robot needlessly slow. Many current methods prioritize point accuracy over the quality of the predicted distribution, or rely on models with millions of parameters. Gaussian processes (GPs) provide uncertainty estimates by design, but GP-based motion prediction had been limited to a few arm joints on small datasets. For my research, I examined whether a structured GP could scale to the full body while staying competitive in distribution quality.
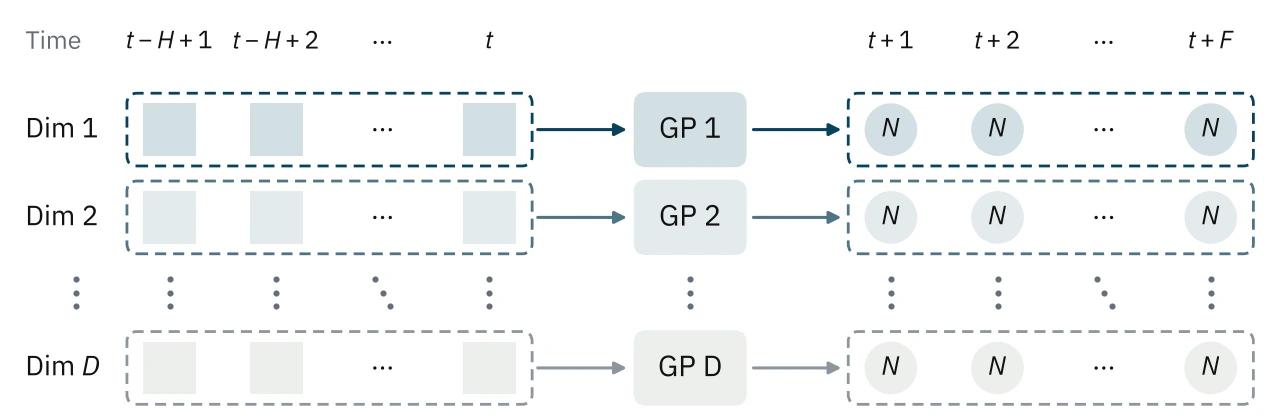
My model predicts the full 2 s horizon in one shot, so uncertainty does not compound over autoregressive rollouts. I factorized it into one sparse variational GP per joint–dimension pair, 96 GPs in total, and each GP couples its future time steps as multitask outputs with a full temporal covariance. A dense covariance over the whole body would take 92 MB per sequence, which this factorization avoids. I represented poses with continuous 6D rotations, then used forward kinematics to rebuild the skeleton while preserving bone lengths. The result is a Gaussian predictive distribution in closed form, so a planner working in rotation coordinates can use it without sampling, density estimation, or forward kinematics.
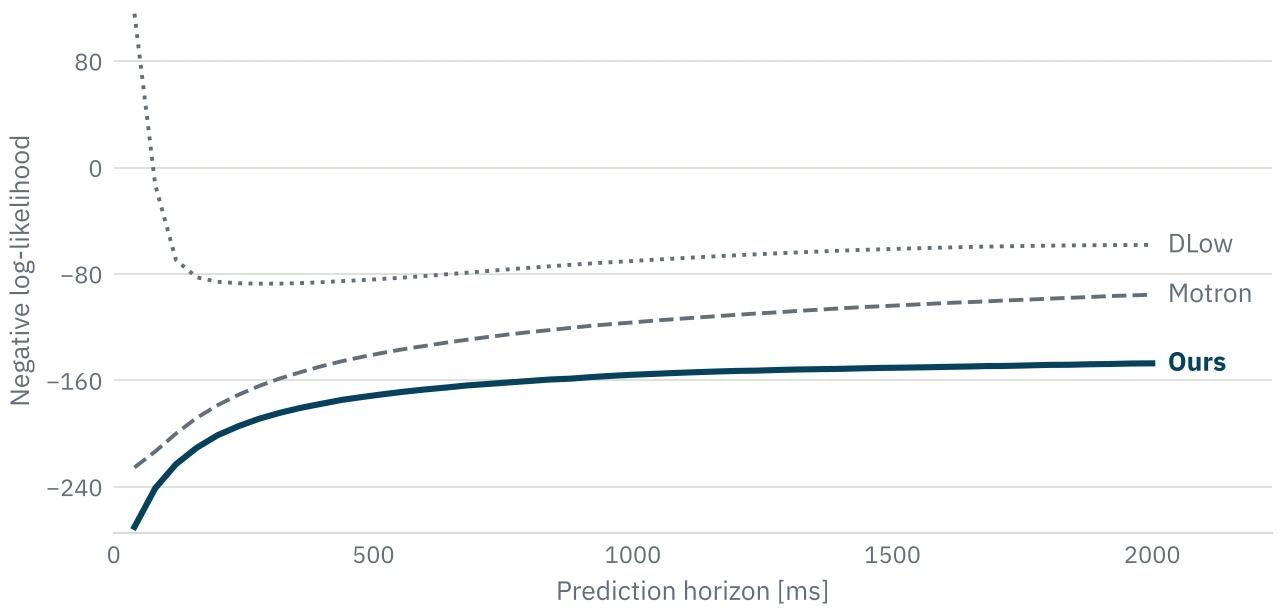
On Human3.6M, the model achieves lower KDE negative log-likelihood than Motron and DLow at every prediction step, 22–52 nats below Motron over the 2 s horizon. Its empirical coverage is conservative at the 50% and 80% levels and close to nominal at 95%. The probabilistic model uses 0.24 M parameters, about seven times fewer than Motron. A separately trained 0.35 M-parameter deterministic variant has a mean angle error 3–22% higher than Motron’s, a gap that narrows to 3% at 1 s. Ablations confirmed the benefit of the 6D representation, and showed that at a fixed training budget, factorized joint outputs beat coupled alternatives while using less memory.
There are tradeoffs. The model is trained for predictive likelihood rather than sample diversity, so its best-of-50 displacement errors are higher than those of most baselines. Joints are also predicted independently, and the evaluation covers a single benchmark of single-subject activities, so the benefit for robot behavior is still to be shown. Next, I want to integrate these distributions into closed-loop planners and test them on human–robot interaction tasks.
I also released a public preprocessing pipeline that reconstructs the now-unavailable exponential-map archive of Human3.6M used in prior work, with verification and 3D visualization tools. The paper is under review for ICRA 2027.