Perception Metrics for Safe Human–Robot Collaboration
Two new safety metrics, Critical and Average Collision Probability, turn a detector's missed detections, position error, and latency into a collision risk. Guided by them, an attentive processing strategy made YOLOv7 detectors 24–30% faster at nearly unchanged accuracy and cut collision probability by up to 13.5% on 243,000 benchmark frames.
Object detection benchmarks rank models by accuracy, and sometimes by frames per second, but rarely ask what either number means for safety. In human–robot collaboration they interact: a detector that is accurate but slow still reports where a hand was, not where it is now. Our ICRA 2024 paper models how three families of perception metrics, namely detection rate, detection quality, and latency, translate into the chance of a collision between a robot and a person.
The model follows two objects, such as a robot’s end effector and a person’s hand, as they move relative to each other in the camera frame. It defines when a collision occurs from their relative position and velocity, then accounts for missed detections, errors in the detected position, and processing delay. From this model, we derived two safety metrics: Critical Collision Probability (CCP) and Average Collision Probability (ACP).
To show that the metrics can guide algorithm design, we proposed an attentive processing strategy. Instead of running a large detector on the full frame, it crops the regions that matter, packs them into a smaller input, and processes that input with a network chosen from an ensemble.
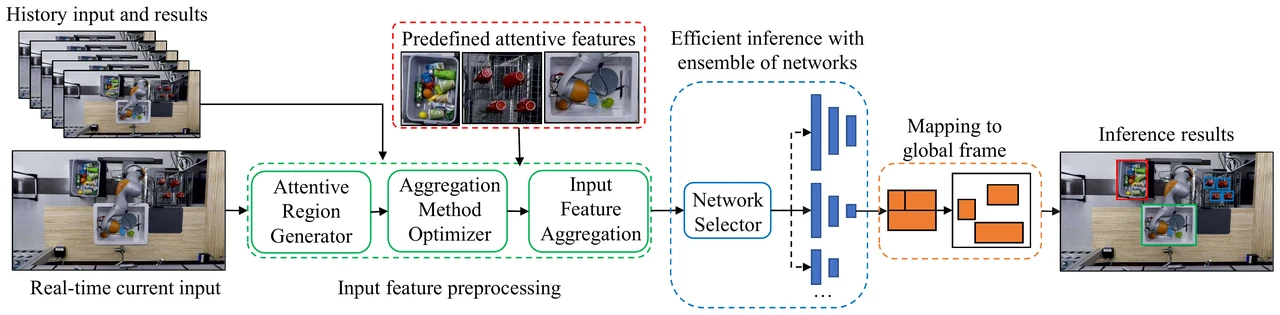
I joined the project as an undergraduate researcher through MIT’s UROP program. I searched for and prepared the evaluation data, and I produced the results section of the demonstration video at the top of this page.
We evaluated the strategy on 79 videos from the LaSOT tracking benchmark, about 243,000 frames, with three YOLOv7 models of increasing size. It reduced inference time by 24–30% and total time per frame by 19–27%, while accuracy measures changed by about 1.5% or less. Those savings carried through to safety: CCP fell by 6.5–11.3% and ACP by 7.3–13.5%, with the largest gains on the largest model.
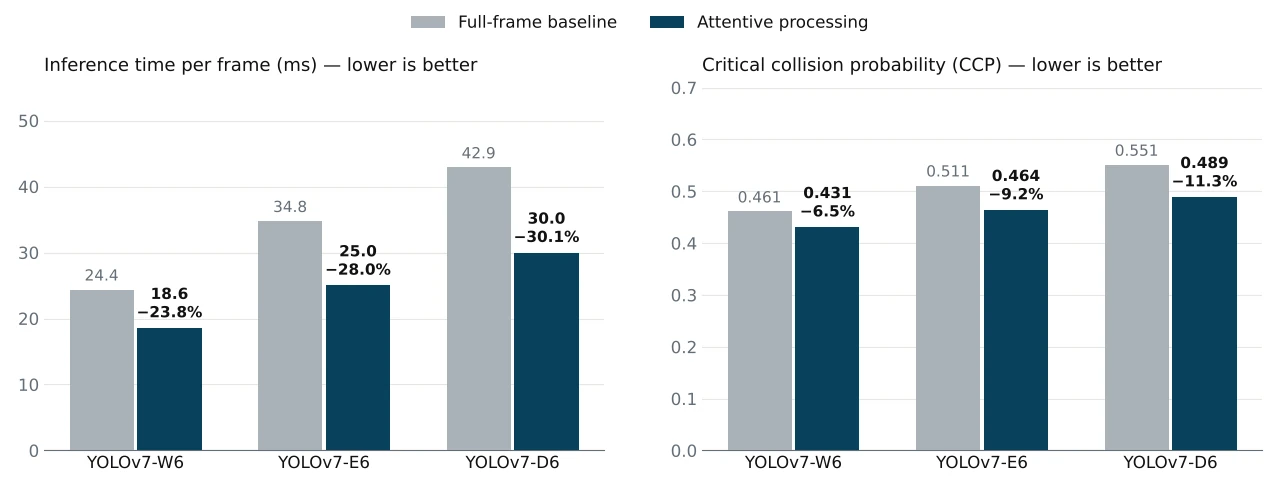
That largest model was the most accurate on the benchmark, yet its slow processing made it the most dangerous for collaboration, a clear case of why speed–accuracy tradeoffs belong in safety analysis. The results come from offline evaluation on a single-object tracking benchmark rather than a closed-loop robot. Most of the remaining accuracy loss came from the smaller networks in the ensemble, which we expect fine-tuning on cropped inputs to recover.