Temporal-Difference Learning for 2048
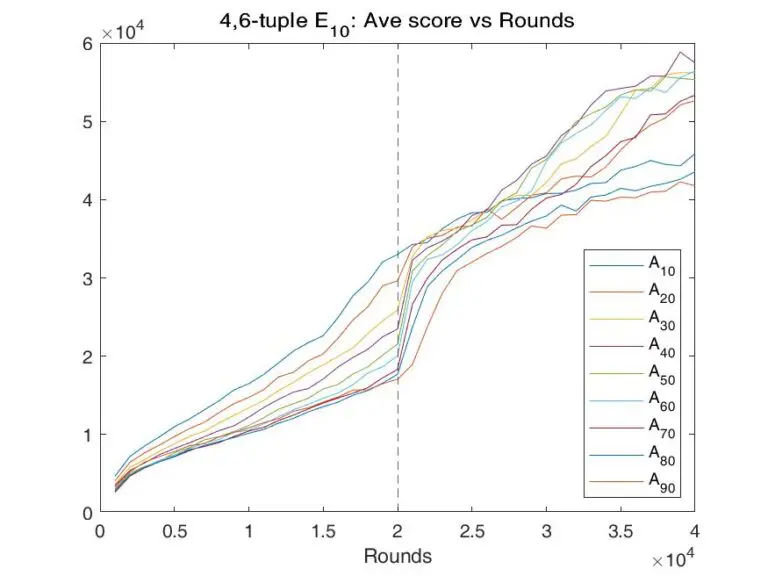
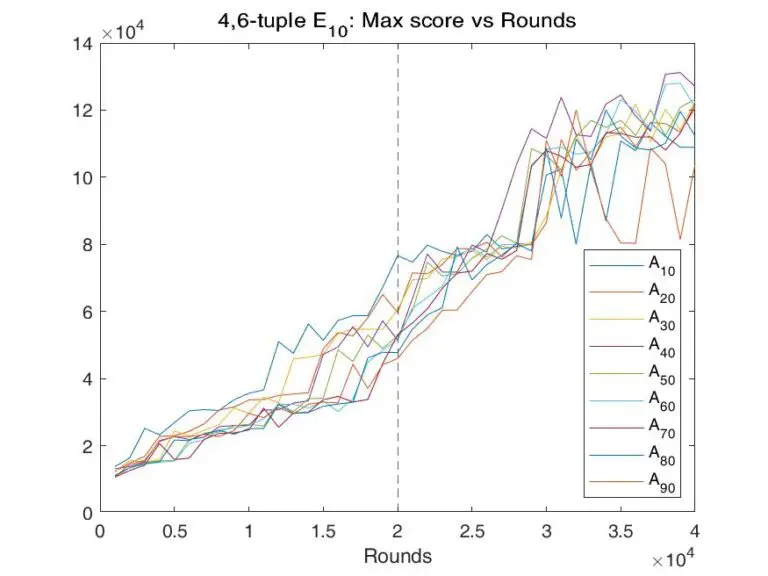
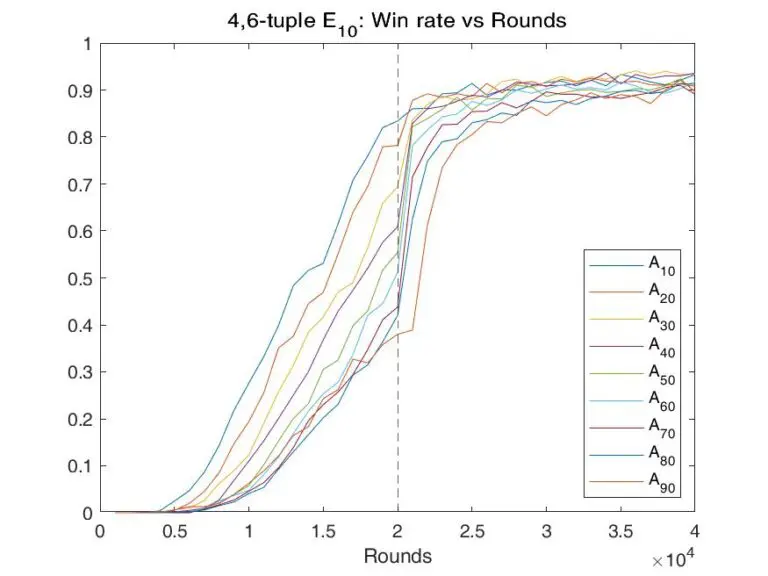
A temporal-difference learning agent, written in C++, learns to play 2048 from self-play. It first reached the 2048 tile after 2,000 training rounds and won 93% of games after 20,000, and the study measures how the chance of spawning a 4-tile affects score and learning speed.
2048 is simple to play but hard to master, because new tiles appear at random after every move. During a research internship at National Chiao Tung University’s Computer Games and Intelligence Lab, I trained a temporal-difference learning agent to play it. The agent learns a value function over board states from its own games and picks each move greedily with respect to that estimate.
The agent first reached the 2048 tile after 2,000 training rounds and hit a 93% win rate after 20,000. I also varied how often the game spawns a 4-tile instead of a 2-tile, to see how that randomness affects the final score and how quickly the agent learns.